AI acceleration for transient CFD skips the startup transient entirely. A standard solver marches forward from an initial condition. It waits until the cyclic flow settles into a repeating pattern. A physics-informed neural network can skip that step and fit the repeating window directly. This is the core idea in arXiv:2605.18340 (submitted May 2026). The paper reports near-identical accuracy to a standard transient-to-periodic solve — reached in substantially less compute time.
This matters if you run cyclic loads, rotating machinery, or periodic thermal cycles. The physics you care about is the repeating steady state. Your solver still has to survive the transient just to reach it. Below, we walk through what the method changes and what toolchain support looks like now. Then we work through the arithmetic — what skipping the run-up is worth inside a multi-objective sweep.
The Transient Run-Up You Pay for on Every Case
Every unsteady CFD or FEA case that ends in a repeating cycle starts the same way. You specify an initial condition. You integrate forward in time until the transient dies out. Only then does the flow — or the thermal field, or the structural load — settle into a repeating pattern. Only then can you extract one clean period and call the case converged. For turbomachinery blade passing, HVAC duct cycling, or a data center’s daily cooling load, that run-up phase eats real time. In practice, it can consume a third to a half of total wall time. That’s before you have a single usable cycle to post-process.
None of that run-up time buys you engineering data. You don’t design against the startup transient. You design against the periodic state it eventually reaches. That’s the part of the CFD budget that AI acceleration for transient CFD targets. It isn’t a faster solver overall. It’s the removal of a phase that was never the answer you needed.
See also: cfd analysis
What the Periodic PINN Actually Changes
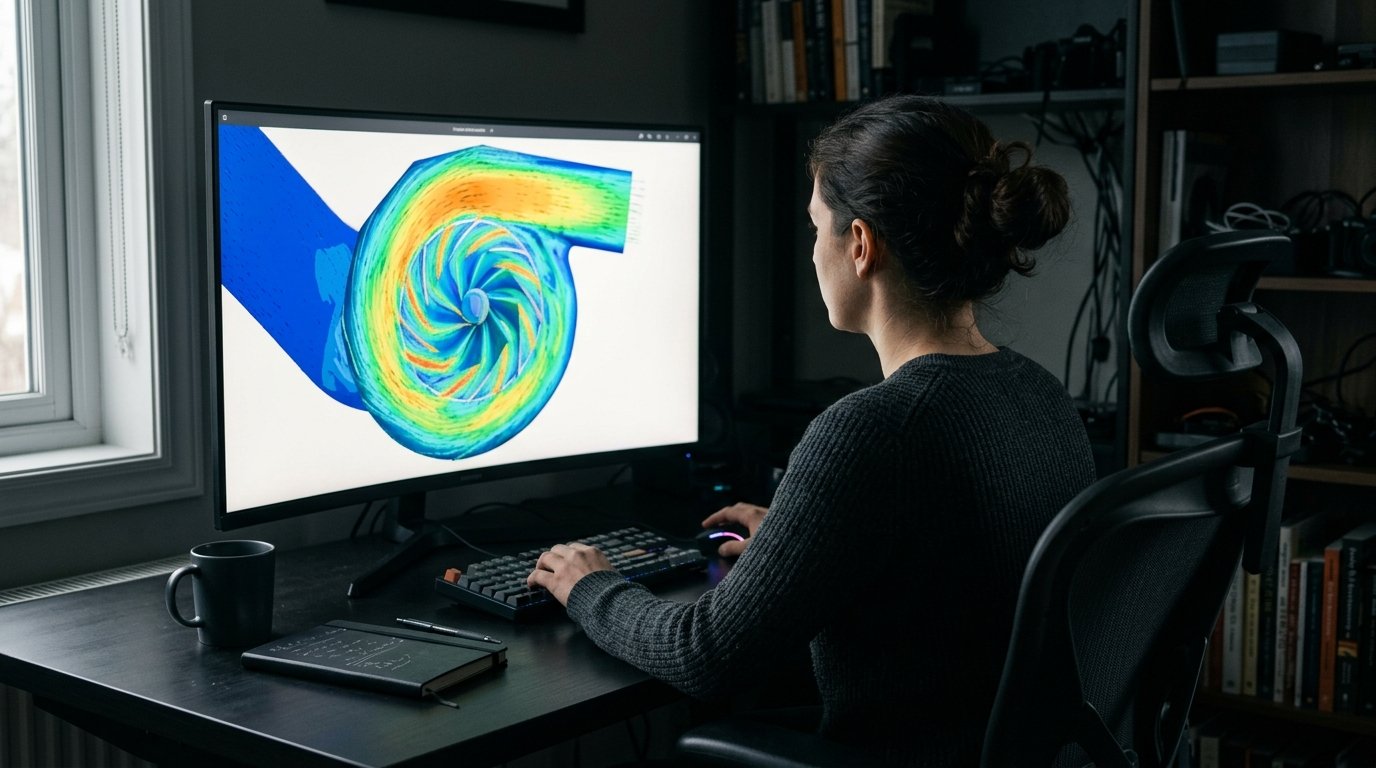
A pinn periodic cfd solver works on a different premise than a standard time-marching solve. A standard solver steps through thousands of time steps from an arbitrary start. This model trains directly on one period of the cycle instead. It’s a physics-informed neural network unsteady flow model, and it’s meshless. It doesn’t discretize a domain into cells the way a finite-volume solver does. Instead, it learns a continuous function that satisfies the governing equations across the periodic window.
The practical payoff is that you skip transient phase cfd simulation work altogether. arXiv:2605.18340 reports the trained model reaches accuracy near-identical to a conventional transient-to-periodic solve. The compute time to get there is substantially lower. For rotating machinery, cyclic thermal loads, or any duty cycle that repeats, this is the phase you don’t need. You only need the cycle itself.
Toolchain Support Is Catching Up
Training a periodic PINN at production scale needs infrastructure most CFD teams don’t have yet. NVIDIA’s PhysicsNeMo 26.08 release adds pieces aimed at exactly this gap. Its release notes list GPU-native mesh generation, GPU remeshing with field transfer, and distributed training support for large models. None of that is a periodic solver by itself. It’s the infrastructure layer that makes a faster transient cfd with ai approach practical at scale. Without it, this stays a one-off research result instead of something you can run on your own cases.
See also: cfd ai
The Arithmetic for a Multi-Objective Sweep
A single accelerated evaluation is useful on its own. Inside a multi-objective sweep, the savings compound. Multi Optimization’s parallel optimization engine runs hundreds of CFD and COMSOL evaluations per sweep for datacenter cooling and TRNSYS-linked HVAC designs. A typical NSGA-II run might use a population of 40 designs over 30 generations. That’s 1,200 evaluations for one optimization study.
- Each transient-to-periodic CFD case: 10 hours
- Run-up share of that case: about 40%, or 4 hours
- Cases per sweep (40 designs × 30 generations): 1,200
- Compute time saved if the run-up is skipped: roughly 4,800 hours across the sweep
That figure is total compute time, not wall-clock time. You run these evaluations in parallel, across many cores or nodes. Cut the run-up from every case, and the saving shows up as fewer wall-clock hours in every generation. It isn’t just a smaller total core-hour bill. For a data center cooling sweep run against COMSOL, or a TRNSYS-linked HVAC model, that can be the difference between an overnight study and one that runs for a week.
FAQ: AI Acceleration for Transient CFD
Does a periodic PINN replace my CFD solver entirely?
No. It replaces the transient run-up phase for cases that end in a repeating cycle. You still validate the periodic result against reference data. You still use a standard solver for genuinely one-off transients.
Which cases benefit most?
Cases with a clear repeating cycle benefit most. Think turbomachinery blade passing, periodic thermal loads, HVAC duty cycles, and rotating-machinery flow. If your case never reaches a periodic state, this approach doesn’t apply.
Do I need new training infrastructure to use this?
At research scale, no. At production scale, yes. Training these models efficiently benefits from GPU-native meshing and distributed training. That’s what NVIDIA’s PhysicsNeMo 26.08 release adds.
How much faster is it really?
arXiv:2605.18340 reports near-identical accuracy to a standard transient-to-periodic solve, reached in substantially less compute time. The paper doesn’t give one universal speed-up number. The gain depends on how large a share of your run time the transient itself occupies.
Bringing This Into Your Own Sweep
AI acceleration for transient CFD is one piece of a bigger shift. It replaces expensive solver phases with trained models inside a live design loop. Say you’re running multi-objective sweeps against CFD or COMSOL. If the transient run-up is eating your generations, a surrogate can absorb that cost instead of a full solve. See how Multi Optimization approaches this on the AI CFD surrogate modeling page.